Technology & Computing · Data & digital information
Why one database query is fast and the next isn't
See what an index does for a database search, which searches it can't help, and how to read the plan that shows whether the database used it.
What you will learn
- Explain what a table scan costs and what an index offers instead
- Say who decides whether an index is used and what that decision depends on
- Decide whether a condition is in a form a B-tree index can use
- Match an index type to the shape of the data being searched
Lesson 1 of 4 · 6 min
Why a database search can mean reading every row
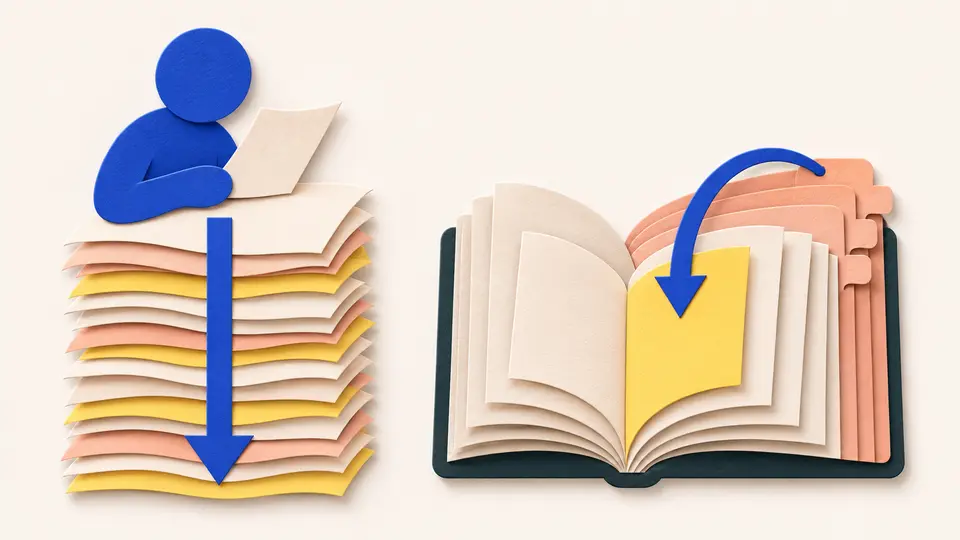
Imagine finding every mention of tides in a 600-page book that has no index. You'd start at page one and read to the end. A database with no preparation does the same. Asked for the rows where the id equals one value, it scans the whole table, row by row.
The answer comes out right. The waste is the problem. If the table holds a million rows and one of them matches, nearly all of that reading was for nothing.
The fix is the one at the back of the book. An index collects the terms readers look up, in alphabetical order, with the pages where each appears. You scan a short list and turn straight to the right page.
A database index does the same job for one column of a table. Once it exists, the database can walk a few levels down a search tree to the matching rows, where before it had to visit every one.
Someone still has to decide what gets indexed. A book's author guesses which terms readers will look up, and whoever designs the database guesses which searches will be common. Nobody indexes every word. The guess can be revised, because an index can be added or removed at any time.
Once you create an index, the database looks after it. It updates the index every time the table changes. And it uses the index in a query only when it expects that to beat reading the whole table, which is called a sequential scan.
So an index gives permission and no instruction. A part of the database called the planner decides again for every query, and sometimes reading everything really is cheaper. When a table fits in a single disk page, PostgreSQL nearly always reads the page and ignores the index. One page has to be fetched either way, so a detour through the index only adds work.
The planner decides from statistics it keeps about each table, such as how many rows it holds. Those go stale as the data changes. A command called ANALYZE refreshes them, and it may need running regularly. A planner with old figures is planning for a table that no longer exists. That's one way a query stays slow with a good index right beside it.
Indexes help more than searches. An update or delete has to find its rows before changing them. So does a join, which matches up rows from two tables.
Try to recallA database has an index on exactly the column a slow query filters on, yet the query is still slow. Give two different things that could be true here.
First, an index is permission and no instruction. The planner uses it only when it expects that to beat a sequential scan, so it may have decided otherwise. Second, the planner decides from statistics. If ANALYZE hasn't run lately, those describe an older version of the table, and the choice rests on stale information.
A third possibility is that the planner is right. On a very small table, or for a query that wants most of the rows, reading straight through really is cheaper.
So when a query is slow, "is there an index?" is the wrong first question. Ask what the planner did with it. The planner may have skipped the index because its statistics are stale, or because reading the whole table was honestly cheaper.
Lessons in this topic
Why a database search can mean reading every row
Without an index, a database checks every row to find a few. See how an index fixes that, and why the database may still decide to ignore it.
Why "starts with" is fast and "contains" is slow
The default database index keeps values in sorted order. See which searches that order speeds up, and which need a different kind of index.
How to read a database's plan for your query
Ask a database how it will run a query and it shows a plan with cost estimates. Learn to read them, and watch the plan change as a search narrows.
Why an index isn't free
Check a database's plan against a real run, then count what every index costs each time the data changes.
Three quick stories from this topic
Timing a delete deletes
PostgreSQL's command for timing a query really runs it, so timing a delete deletes rows
EXPLAIN ANALYZE runs the query and prints true times and row counts beside the planner's estimates. Any side effects happen as usual. To test a delete safely, the manual says to run it inside a transaction and roll it back.
A forecast you can check
Plain EXPLAIN only shows the plan and its cost estimates. Adding ANALYZE executes the query so the estimates can be compared with what happened.
What to look for
The manual says the most important thing is usually whether the estimated row counts are reasonably close to reality.
Starts with, not contains
PostgreSQL's standard index finds names starting with "mar" but not names containing "son"
The standard index keeps values in sorted order, like a phone book. Names with the same beginning sit together in one stretch. Names that share a middle are scattered through the whole list, so every entry has to be read.
Sorted order is the whole trick
The default index type, a B-tree, handles exact matches and ranges because each is one unbroken stretch of the sorted values. A pattern has to be anchored to the start of the text to count.
Other questions, other indexes
PostgreSQL has other index types for other shapes of question. A GIN index, for one, keeps a separate entry for every item inside a value such as an array.
Tiny tables skip indexes
PostgreSQL nearly always ignores an index on a table that fits in one disk page
The database picks the cheapest way to answer each query. A one-page table costs one disk read whatever happens, so looking in an index first would only add reads. An index gives permission to take a shortcut, and the planner can decline.
The planner decides every time
Once an index exists, PostgreSQL uses it in a query only when it thinks that would be more efficient than reading the whole table. It makes that call again for each query.
Toy tables mislead
The manual warns that results on a toy-sized table can't be assumed to apply to large ones. The planner might choose a different plan as a table grows or shrinks.
Sources
- PostgreSQL 18 Documentation: 11.1. Introduction (Indexes), The PostgreSQL Global Development Group
- PostgreSQL 18 Documentation: 14.1. Using EXPLAIN, The PostgreSQL Global Development Group
- PostgreSQL 18 Documentation: 11.2. Index Types, The PostgreSQL Global Development Group